 AsimAli
Data extraction is one of the most common tasks businesses deal with every day. Companies receive invoices, forms, contracts, emails, reports, receipts, applications, and other documents containing information that needs to be entered into business systems. 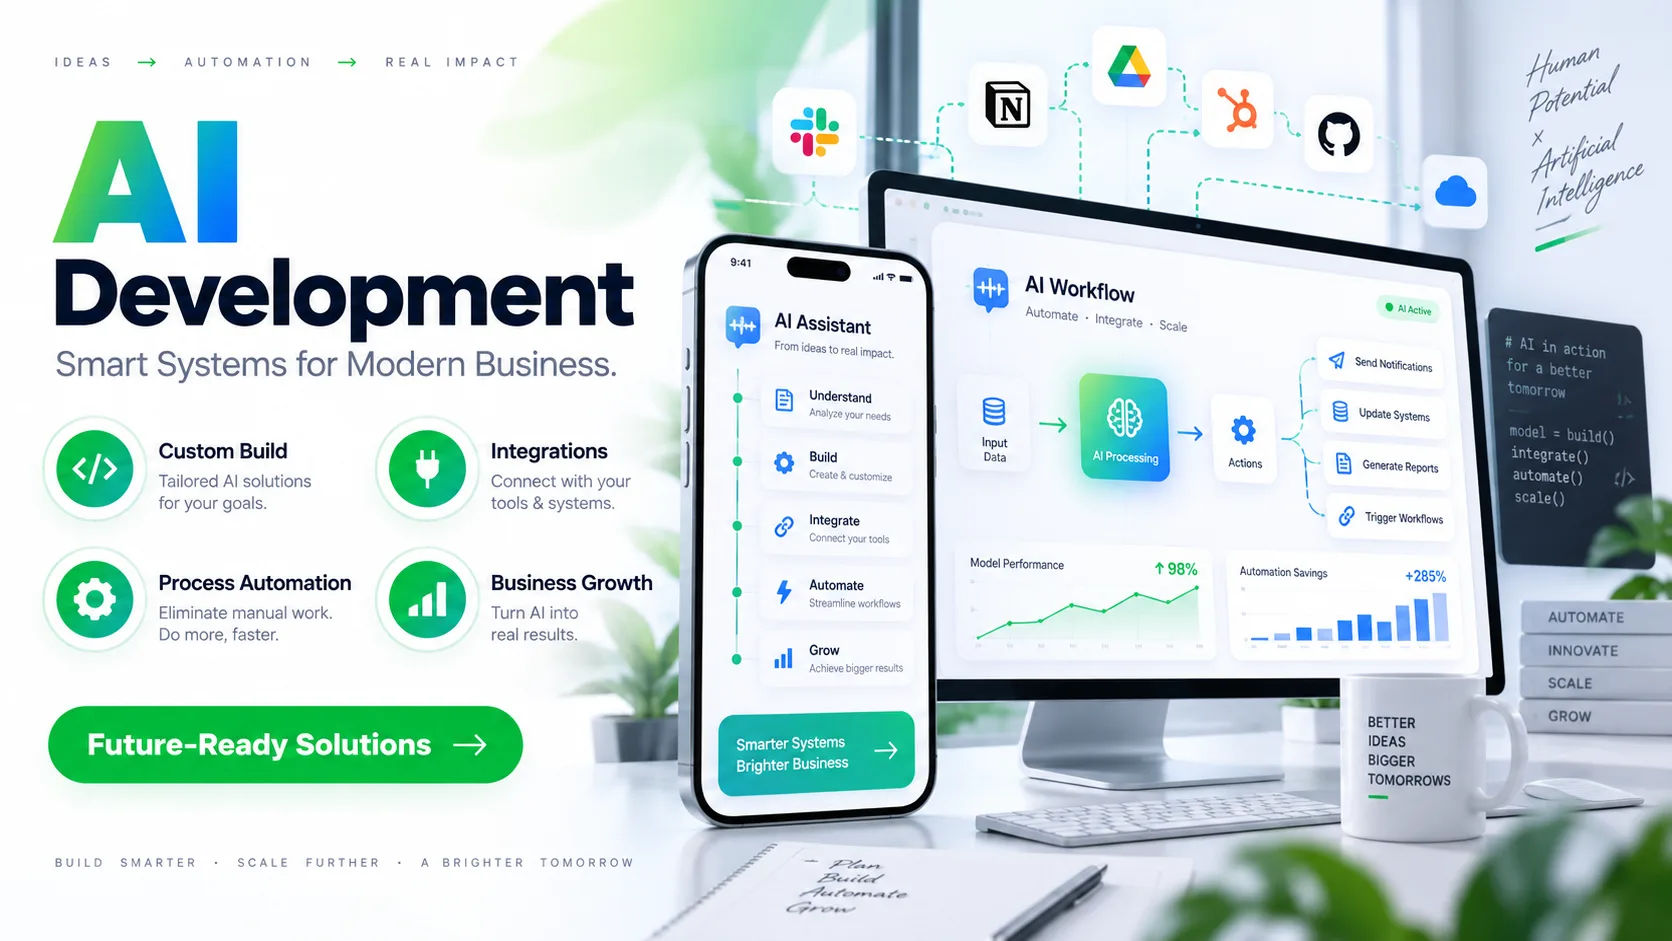 When this work is done manually, employees can spend hours reading documents, copying information, checking fields, and moving data between applications.
This is where automation can make a practical difference. Instead of asking employees to process every document from beginning to end, automated systems can identify useful information and move it into the appropriate workflow. The technology can work with both structured information, such as spreadsheets, and less organized content, such as emails and scanned documents.
Intelligent automation solutions can extract data by combining technologies such as optical character recognition, artificial intelligence, machine learning, natural language processing, and workflow automation. The system can identify relevant information, interpret what that information means, validate important fields, and send the extracted data to another application or process.
How Data Extraction Works
Data extraction sounds simple when described as "reading information from a document," but there are several steps involved. A reliable extraction process needs to locate the document, understand its format, identify useful fields, capture the information, and determine whether the extracted results are accurate.
The exact process depends on the type of information being handled. A spreadsheet with clearly labeled columns is relatively easy to process. A scanned invoice, handwritten form, or long contract requires more advanced techniques.
Capturing the Source Document
The first step is getting the information into the automation system.
Documents may arrive through email attachments, cloud storage, business applications, online forms, document management systems, or direct uploads. Some organizations also receive physical documents that must first be scanned.
Once the document reaches the system, it can be prepared for processing.
For example, a scanned invoice may contain a mixture of text, numbers, logos, tables, and formatting. The system needs to identify the relevant areas before it can extract useful information.
Using OCR to Read Text
Optical character recognition, commonly known as OCR, converts text contained in images or scanned documents into machine-readable information.
For example, imagine an organization receives a scanned invoice. A person can look at the invoice and immediately recognize the supplier name, invoice number, date, tax amount, and total.
A computer does not automatically understand those details simply by seeing the image.
OCR helps convert the visible characters into digital text. More advanced systems can then analyze that text to determine what each piece of information represents.
OCR is particularly useful for scanned PDFs, photographs of documents, printed forms, receipts, and other image-based files.
Identifying Important Fields
Extracting text is only part of the job.
A business usually does not need every word from a document. It needs specific information.
For an invoice, that might include the vendor name, invoice number, purchase order number, invoice date, subtotal, tax, and total amount.
For a customer application, the required fields might include the person's name, address, contact information, account number, and application details.
Intelligent automation systems can be configured to identify these fields automatically.
Context
Modern automation can go beyond simply recognizing characters.
Suppose a document contains the number "1,250.00." By itself, that number does not explain anything. It could represent a subtotal, tax amount, payment, balance, or total.
The surrounding text and document structure provide context.
AI-based extraction can analyze labels, nearby text, document layout, and other signals to determine what the number represents.
This ability to understand context is one reason modern automation can handle more complicated documents than traditional rule-based systems.
What Types of Data Can Be Extracted?
Businesses can extract many different types of information through automated processes.
The most common examples include names, dates, addresses, identification numbers, invoice details, payment information, product descriptions, account numbers, contract terms, and contact details.
The technology can also extract information from tables and repeated fields.
Structured Data
Structured data is information that already follows a predictable format.
Spreadsheets and databases are common examples.
A spreadsheet might contain columns for customer name, email address, order number, product, quantity, and price. Since the information is already organized, extraction is usually straightforward.
Automation can read the relevant cells and transfer the information into another system.
Unstructured Data
Unstructured information is more difficult because it does not follow a consistent format.
Emails, contracts, letters, reports, and free-form documents are common examples.
One invoice might place the total amount at the bottom right, while another might display it in a different location. The wording can also vary from supplier to supplier.
This is where AI-based extraction can be useful because it can analyze context rather than relying entirely on fixed positions.
Semi-Structured Documents
Many business documents fall somewhere between structured and unstructured data.
Invoices are a good example.
They usually contain recognizable fields, but different companies use different layouts and terminology.
One supplier may use "Invoice Total," while another may use "Amount Due." Both may refer to the same basic concept.
Automation can be trained or configured to recognize these variations.
Can Automation Extract Data From PDFs?
Yes. PDF extraction is one of the common applications for automation.
The difficulty depends on how the PDF was created.
A digital PDF containing selectable text is generally easier to process than a scanned PDF that is essentially an image.
A scanned document may require OCR before the system can analyze its contents.
Tables can introduce additional complexity because the system must determine which values belong to which rows and columns.
Poor scans, unusual fonts, distorted pages, and complex layouts can also reduce extraction accuracy.
For that reason, organizations should not assume that every PDF can be processed perfectly without validation.
Can It Extract Data From Emails?
Email is another practical use case.
Businesses often receive important information directly through email. This may include customer requests, purchase orders, invoices, shipping information, applications, or support details.
An automated system can monitor designated inboxes, identify relevant messages, read attachments, extract information, and send the results into another workflow.
For example, a purchase order received by email could be processed automatically. The system might identify the customer, order number, products, quantities, and requested delivery date.
The information can then be transferred to an enterprise resource planning system or another business application.
This can reduce the amount of manual copying required from employees.
How Intelligent Automation Handles Different Document Formats
A major advantage of intelligent automation solutions is their ability to work across different document types.
A business may receive Word documents, PDFs, spreadsheets, scanned forms, images, emails, and online submissions.
Instead of creating an entirely separate manual process for every format, automation can route different inputs through appropriate processing steps.
A PDF might go through text extraction and OCR.
A spreadsheet might be processed directly through its rows and columns.
An email might be analyzed for both its message content and attachments.
The workflow can then bring the extracted information into a common business process.
How Accurate Is Automated Data Extraction?
Accuracy depends on several factors.
The quality of the source document matters. A clear digital document is easier to process than a blurry photograph.
The document layout matters as well.
The extraction technology also matters. Some systems rely heavily on fixed rules, while AI-based systems can interpret more variations.
Validation procedures are equally important.
Even advanced systems can make mistakes. A decimal point can be misread. A character can be confused with a number. A field can be assigned the wrong meaning.
That is why good intelligent automation solutions do not simply extract information and assume that everything is correct.
They can include validation rules and confidence checks.
The Role of Human Review
Automation does not always need to eliminate people from the process.
In many cases, the better approach is to let automation handle routine documents while sending uncertain cases to employees.
For example, suppose an extraction system is highly confident about an invoice number and total amount but uncertain about the purchase order number.
The system can process the reliable fields and flag the uncertain field for review.
An employee can then check the original document and correct the information.
This creates a balance between automation and human judgment.
Human review is especially valuable when documents contain unusual layouts, missing information, handwriting, poor-quality scans, or ambiguous language.
Data Validation After Extraction
Extraction should not be treated as the final step.
The information should often be checked before it enters an important business system.
Validation can include checking whether required fields are present, whether dates use an acceptable format, whether numerical values are reasonable, and whether extracted identifiers match existing records.
For financial documents, the system may also compare totals with line items.
For customer information, it may check whether an account already exists.
These checks can prevent incorrect information from spreading through other systems.
Connecting Extracted Data to Business Systems
Extracted information becomes more useful when it can move directly into existing applications.
For example, invoice information might be sent to accounting software.
Customer details might be added to a CRM.
Order information might be transferred to an ERP system.
Claims information might move into an insurance processing platform.
This connection is often handled through APIs, integrations, connectors, or other data exchange methods.
The objective is to avoid creating another isolated database that employees must manage manually.
API Integration
An API allows different software applications to communicate through defined methods.
For example, an extraction system can send a customer name, order number, and payment information to another application through an API.
The receiving application can then process the information according to its own rules.
This makes automation more useful because extracted data can immediately become part of an existing workflow.
Common Business Uses
There are many practical situations where automated data extraction can save time.
Accounts payable departments can extract invoice information.
Human resources teams can process employee forms.
Customer service departments can capture information from incoming requests.
Logistics companies can extract shipping details.
Healthcare organizations can process certain administrative documents.
Insurance companies can extract information from claims documentation.
Legal teams can identify specific information within large collections of documents.
The exact application varies, but the underlying idea remains similar: identify useful information and move it into the next stage of the process.
What About Handwritten Information?
Handwriting presents a greater challenge than clean, printed text.
Some advanced systems can recognize certain types of handwriting, but results vary significantly depending on legibility, writing style, document quality, and the technology being used.
A clearly written number may be recognized correctly, while rushed or unclear handwriting may produce errors.
Organizations that depend heavily on handwritten forms should test the technology using real documents before implementing it at scale.
A human review process may remain necessary for difficult cases.
Can It Extract Information From Contracts?
Yes, but contracts require a different approach from simple forms.
A contract may contain long paragraphs, legal terminology, clauses, dates, names, obligations, and exceptions.
The system may be configured to identify specific information, such as renewal dates, payment terms, contract values, termination clauses, or particular obligations.
Natural language processing can help analyze the text and identify relevant sections.
However, contract extraction should be handled carefully. Identifying a clause is not necessarily the same as understanding every legal implication of that clause.
For sensitive legal work, human review remains important.
Security and Privacy Considerations
Data extraction often involves sensitive business information.
Documents may contain customer information, financial records, employee details, contracts, or confidential business data.
Organizations therefore need to consider how documents are stored, processed, transferred, and accessed.
Access controls should restrict sensitive information to authorized users.
Data should also be protected during transmission and storage where appropriate.
Businesses should understand what happens to their information within the automation platform, particularly when third-party AI services are involved.
Security should be considered before implementation rather than added as an afterthought.
Challenges of Automated Data Extraction
Automation can provide significant efficiency improvements, but it is not magic.
One challenge is document variability.
If every supplier uses a different invoice design, the extraction system needs to handle those differences.
Another challenge is poor-quality input.
A system cannot reliably extract information that is barely visible or severely damaged.
There can also be problems with ambiguous information.
For example, a document might contain several dates. The system must determine which date represents the invoice date, due date, delivery date, or contract date.
Integration can create another challenge.
Even if the extraction process works correctly, the destination system must be able to receive and process the information properly.
How to Implement Data Extraction Successfully
A sensible implementation usually starts with a clearly defined business problem.
Instead of trying to automate every document immediately, an organization can begin with one document type that has a high volume and relatively clear requirements.
The current manual process should be mapped first.
This helps identify where employees spend time, where errors occur, and where decisions are being made.
Next, the organization can select the extraction technology and test it against real examples.
Testing should include normal documents as well as difficult cases.
The organization should measure extraction accuracy, processing time, exception rates, and the amount of human intervention required.
Only after the process performs reliably should it be expanded.
Measuring the Results
The success of intelligent automation solutions should be measured using practical business metrics.
Processing time is one useful measure.
If a task previously required several hours and automation reduces the workload significantly, the difference can be measured.
Accuracy is another important metric.
Organizations should track how often extracted information requires correction.
Exception rates can also provide valuable information.
A high exception rate may indicate that the documents are too inconsistent or that the extraction process needs improvement.
Businesses should also measure how much manual work remains after implementation.
When Should Humans Stay Involved?
Some processes are suitable for almost complete automation.
Others need human involvement because the consequences of an error are significant.
A useful approach is to separate routine decisions from complex decisions.
Automation can process predictable information.
Employees can handle unusual cases, exceptions, or decisions requiring judgment.
This approach can reduce repetitive work without forcing automation into situations where human expertise remains important.
The Future of Automated Data Extraction
Data extraction is becoming more connected to broader business automation.
Instead of simply extracting information into a spreadsheet, future workflows can use extracted data to trigger actions.
For example, an invoice can be received, analyzed, validated, matched against a purchase order, routed for approval, and entered into an accounting system.
The extraction stage becomes one component of a larger automated process.
This is where intelligent automation solutions can provide value beyond simple document reading.
They can connect information capture with decisions, validation, communication, and workflow execution.
The technology is also becoming better at handling different forms of information. Text, tables, images, and documents can increasingly be processed within connected workflows.
However, better technology does not remove the need for good process design.
A poorly designed process can still produce poor results even when the underlying AI is capable.
Conclusion
Yes, intelligent automation can extract data from many different sources, including PDFs, invoices, emails, forms, spreadsheets, scanned documents, and other business records.
The process usually combines document capture, OCR, AI-based interpretation, field identification, validation, and integration with existing business systems.
The biggest advantage is not simply that a computer can read a document. The real value comes from what happens after the information has been extracted.
When data can move automatically into accounting software, CRM platforms, ERP systems, document management tools, or other applications, businesses can reduce repetitive manual work and create faster workflows.
At the same time, automation should not be treated as perfectly accurate. Document quality, unusual layouts, handwriting, ambiguous information, and integration problems can all affect results.
That is why effective intelligent automation solutions normally include validation and exception handling. Human employees can review uncertain cases while routine documents continue through the automated process.
For organizations considering this technology, starting small is often practical. Choose a process with clear requirements, collect real examples, test extraction accuracy, measure exceptions, and improve the workflow before expanding it.
Data extraction is therefore not just about replacing manual typing. Done properly, it can become part of a larger system that captures information, checks it, routes it, and turns it into useful business action. The strongest implementations combine capable technology with sensible workflows, reliable data, security controls, and appropriate human oversight.
